A practical testing strategy for validating AI behavior, managing output variation, and keeping CI/CD pipelines reliable
AI-native applications create a testing problem that traditional CI/CD pipelines were not designed to handle: the same input can produce different model outputs across runs. This guide explains how to test non-deterministic model outputs using structured evaluation criteria, thresholds, regression datasets, safety checks, and staged deployment controls without treating every output difference as a failure.
Table of Contents
- 1. Topic Introduction
- 2. Why AI-Native CI/CD Testing Matters
- 3. How to Test Non-Deterministic Model Outputs
- 4. When to Run AI Model Tests
- 5. 8 Ways to Test Non-Deterministic Model Outputs
- 6. Building a Practical AI CI/CD Test Pipeline
- 7. Handling Test Failures
- 8. CI/CD Design for AI Applications
- 9. Conclusion
Traditional CI/CD testing usually expects predictable results. Give the same input to the same function, and the test expects the same output. AI applications are different. Model responses can change because of sampling, model updates, prompt changes, retrieved context, tool results, or changes in surrounding application logic.
That does not mean AI systems cannot be tested reliably. The testing strategy needs to change from exact output matching to measurable behavioral requirements. This approach helps development teams detect regressions while allowing acceptable variation in model responses.
Why AI-Native CI/CD Testing Matters
- Exact matches fail: AI responses can vary while still satisfying the application’s requirements.
- Small changes matter: A prompt, model, retrieval configuration, or system instruction can change downstream behavior.
- Manual testing scales poorly: Teams cannot manually review every model response for every deployment.
- Silent regressions hurt: A model can remain available while becoming less accurate, less safe, or less useful.
- Deployment needs evidence: CI/CD pipelines need measurable signals before allowing AI-related changes into production.
How to Test Non-Deterministic Model Outputs
| Testing Aspect | Recommended Strategy | Example |
| Output correctness | Test required properties instead of exact wording | Required fields exist |
| Factual quality | Compare against trusted reference data | Key facts remain accurate |
| Classification | Measure expected class or score | Precision and recall thresholds |
| Structured output | Validate schema and types | Valid JSON response |
| Safety | Test prohibited behaviors | No sensitive information leakage |
| Retrieval | Evaluate relevant context | Expected documents are retrieved |
| Regression | Maintain a fixed evaluation dataset | Compare against previous baseline |
| Performance | Track latency and token usage | Stay within service limits |
The goal is to define what must remain stable even when the exact model response changes.
When to Run AI Model Tests
| Pipeline Stage | Test Type | Purpose |
| Pull request | Fast validation | Catch prompt, code, and schema errors early |
| Build | Evaluation subset | Check core model behavior |
| Staging | Full evaluation | Measure broader quality before release |
| Pre-production | Safety and regression | Verify release-level requirements |
| Deployment | Smoke tests | Confirm production integration |
| Scheduled runs | Regression suite | Detect model or data drift |
| After model changes | Full evaluation | Compare the new model with the baseline |
Not every test needs to run on every commit. Fast checks should protect developer feedback time, while larger evaluation suites can run before staging or production deployment.
8 Ways to Test Non-Deterministic Model Outputs
1. Test Properties Instead of Exact Responses
- Check required fields: Confirm that structured responses contain all mandatory fields.
- Validate constraints: Check length, format, allowed values, and required content.
- Measure intent: Verify that the response addresses the requested task.
- Ignore wording: Avoid failing a test because two valid responses use different sentences.
- Check structure: Validate JSON, XML, Markdown, or other required response formats.
2. Build a Fixed Evaluation Dataset
- Collect real cases: Use representative inputs from production scenarios.
- Include edge cases: Add ambiguous, incomplete, and unusual inputs.
- Store expected criteria: Define what a successful response must contain or achieve.
- Version datasets: Track changes to evaluation cases over time.
- Protect sensitive data: Remove unnecessary customer or proprietary information.
3. Use Threshold-Based Evaluation
- Set quality thresholds: Define the minimum acceptable score for each important metric.
- Measure aggregates: Evaluate performance across multiple test cases.
- Track critical failures: Treat severe failures differently from minor quality changes.
- Allow variation: Do not reject releases because of small, acceptable score differences.
- Document limits: Make threshold decisions explicit and reviewable.
4. Add LLM-Based Evaluation Carefully
- Define evaluator criteria: Give the evaluator a clear scoring rubric.
- Use reference answers: Provide supporting context when judging factual correctness.
- Limit evaluator scope: Use automated evaluation for measurable criteria.
- Sample failures: Manually review important failed cases.
- Track evaluator changes: Keep evaluator prompts and models versioned.
5. Test Structured Outputs Separately
- Validate schemas: Confirm that model responses match the expected schema.
- Check data types: Reject strings where numbers or arrays are required.
- Test missing fields: Verify application behavior when fields are absent.
- Test invalid values: Reject values outside defined constraints.
- Handle malformed output: Confirm that the application fails safely.
6. Add Safety and Security Tests
- Test sensitive data: Check whether the model exposes protected information.
- Test prompt injection: Include malicious instructions in evaluation inputs.
- Test access boundaries: Confirm that responses respect authorization rules.
- Test unsafe requests: Verify expected refusal or safe handling behavior.
- Check tool usage: Confirm that the model cannot invoke tools outside its intended scope.
7. Compare Against a Baseline
- Save baseline results: Record evaluation metrics for the current production version.
- Compare releases: Measure the candidate version against the baseline.
- Track individual cases: Aggregate scores can hide serious failures.
- Set regression limits: Define how much degradation is acceptable.
- Review trade-offs: A quality improvement in one metric can sometimes reduce another.
8. Separate Model Tests From Application Tests
- Test application logic: Verify deterministic code independently from model behavior.
- Test model behavior: Evaluate prompts, model responses, and AI-specific requirements separately.
- Test integrations: Validate retrieval, tools, APIs, and data pipelines independently.
- Test end-to-end flows: Confirm that the complete system works together.
- Keep failures traceable: Identify whether a failure came from code, model output, data, or infrastructure.
Building a Practical AI CI/CD Test Pipeline
| Layer | Example Checks | Release Role |
| Unit tests | Application functions and business logic | Required |
| Schema tests | Structured model output | Required |
| Prompt tests | Core expected behaviors | Required |
| Evaluation tests | Quality and relevance metrics | Threshold-based |
| Regression tests | Comparison with baseline | Threshold-based |
| Security tests | Injection and data exposure | Required |
| Integration tests | APIs, tools, retrieval | Required |
| End-to-end tests | Complete user workflows | Pre-release |
This layered approach keeps deterministic testing where it works and introduces statistical or rubric-based evaluation where exact matching is inappropriate.
Handling Test Failures
- Inspect individual cases: Do not rely only on aggregate scores.
- Classify failures: Separate code, model, prompt, data, and infrastructure issues.
- Check severity: Treat security and compliance failures differently from wording changes.
- Compare baselines: Determine whether the candidate actually introduced regression.
- Preserve evidence: Store inputs, outputs, model versions, prompts, and evaluation results.
For production systems, this evidence is useful when investigating why a deployment changed model behavior.
CI/CD Design for AI Applications
A practical release flow can look like this:
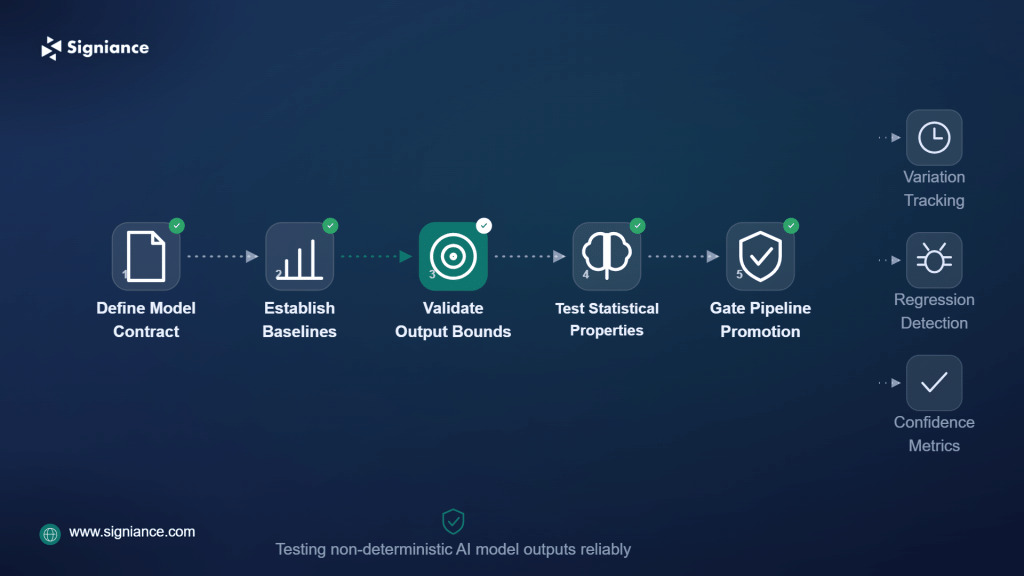
Code or prompt change → Fast tests → Model evaluation → Regression checks → Security checks → Staging evaluation → Deployment → Production monitoring
The important point is that every stage should have a clear purpose.
- Use fast checks: A pull request can use a small representative test set to catch obvious failures.
- Use larger evaluations: Run broader evaluation suites before staging or production.
- Define gates: Give each release stage explicit pass and fail conditions.
- Track changes: Record model, prompt, dataset, and application versions.
- Monitor production: Continue checking quality after deployment instead of treating release as the end of testing.
Conclusion
AI-native CI/CD works better when teams stop treating every model response as a fixed string and start testing the behavior that actually matters. Combine deterministic tests with evaluation datasets, measurable thresholds, regression checks, and safety validation to make model changes easier to release and troubleshoot.
Need help designing reliable AWS AI and DevOps pipelines for AI-native applications? Visit Us Now